
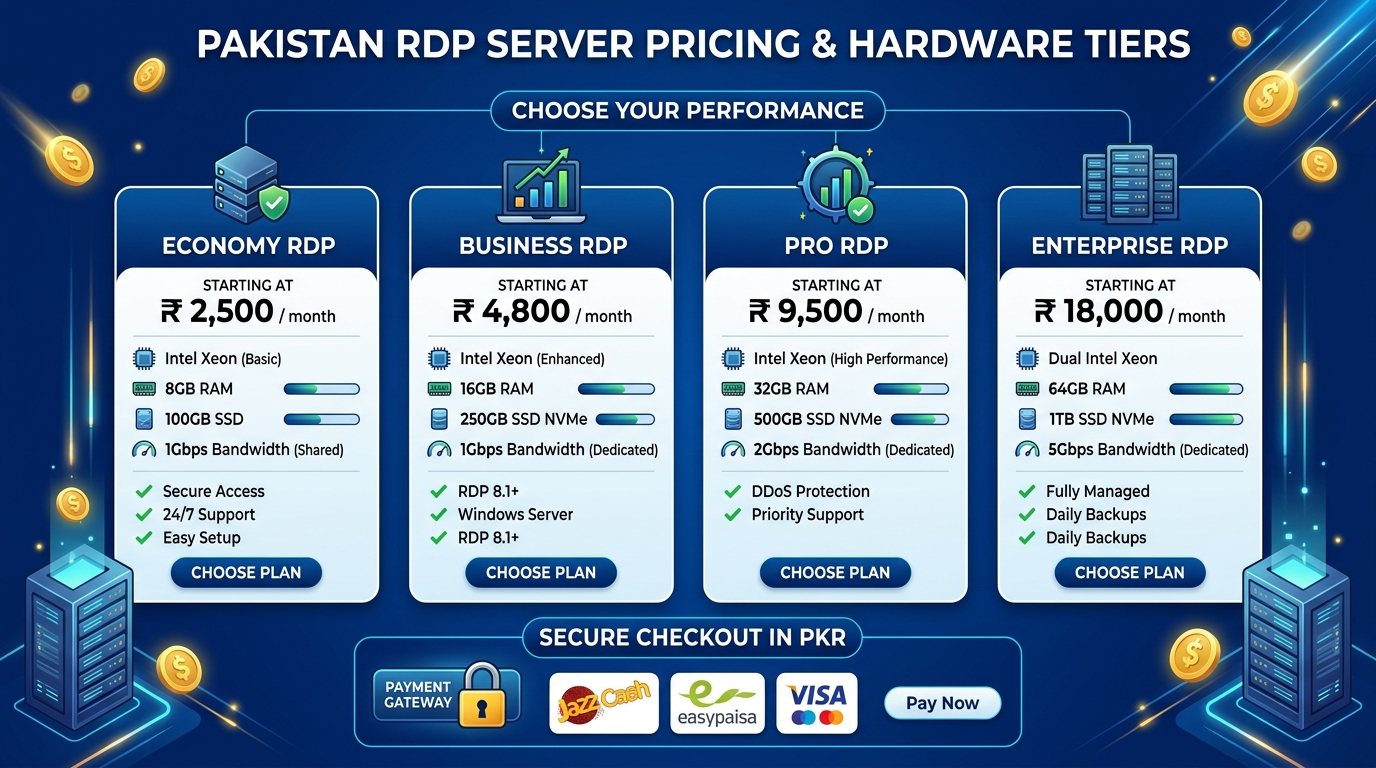
Artificial intelligence engineers, enterprise data scientists, and computational linguistics researchers across Pakistan—from research labs at NUST, FAST-NUCES, and LUMS to enterprise fintechs and software houses in Lahore, Karachi, and Islamabad—face a formidable infrastructure roadblock when training, fine-tuning, and deploying modern Large Language Models (LLMs).
Local development environments frequently suffer from severe hardware limitations: consumer GPU thermal throttling, crippling hardware import tariffs, unstable domestic grid power, and erratic residential ISP upload speeds that render self-hosted client-facing APIs unviable.
┌──────────────────────────────────────────────────────────────────────────────────────────┐
│                   LOCAL DESKTOP VS. BARE-METAL NVMe CLOUD WORKSTATION                    │
├──────────────────────────────────────────────────────────────────────────────────────────┤
│                                                                                          │
│  [ Local Office / Desktop Rig in Pakistan ]                                              │
│  • 12GB - 16GB VRAM Consumer GPU (OOM on 70B / 32B batch training)                       │
│  • Loadshedding & UPS battery failover risks during 14-hour LoRA epochs                  │
│  • Asymmetric residential fiber (slow model checkpoint sync & upload)                    │
│  • Unviable for 24/7 client-facing production API endpoints                              │
│                                                                                          │
│                                     ▼                                                    │
│  [ Dedicated Bare-Metal NVMe VPS / RDP Workstation ]                                     │
│  • High-Frequency Multi-Core Compute (AMD EPYC / Intel Xeon Gold)                        │
│  • Direct PCIe Gen4 NVMe Sustained 7,000 MB/s I/O for Dataset Streaming                  │
│  • 10Gbps Tier-1 Redundant Data Center Uplink (Ultra-fast Hugging Face Pulls)            │
│  • 24/7 99.99% Uptime with Unsloth 2x-5x Accelerated QLoRA & vLLM Serving                │
│                                                                                          │
└──────────────────────────────────────────────────────────────────────────────────────────┘
The professional engineering standard is provisioning a dedicated, high-memory Bare-Metal NVMe Linux/Windows VPS or high-throughput Remote Workstation (RDP). This dedicated environment handles the entire model lifecycle: dataset preparation, tokenizer optimization for Urdu and regional scripts, accelerated parameter-efficient fine-tuning (PEFT/QLoRA), loss optimization, multi-bit GGUF quantization, and high-concurrency inference serving with OpenAI-compatible API endpoints.
This masterclass technical guide delivers a complete, reproduction-ready blueprint for configuring, training, quantizing, and deploying open-weights models (such as Llama 3.3 70B/8B, Qwen 2.5 14B/32B/72B, and DeepSeek-R1-Distill) on high-performance cloud server infrastructure.
1. High-Performance Server Architecture & Host System Sizing
Training and fine-tuning transformer models demand strict hardware resource allocation. Unlike standard web workloads, LLM training generates sustained tensor operations that push memory bandwidth, CPU interconnects, and NVMe disk caching to peak saturation.
Minimum vs. Enterprise Recommended Hardware Specifications
| Workload Dimension | Entry-Level Fine-Tuning (8B Models) | Production Enterprise (14B - 70B QLoRA) |
|---|---|---|
| Compute Processor | 8 vCPU (AMD EPYC / Xeon Gold) | 16 - 32 Dedicated vCPUs |
| System Memory (RAM) | 32 GB DDR4/DDR5 ECC | 64 GB - 128 GB DDR5 ECC |
| Storage Architecture | 200 GB PCIe Gen4 NVMe SSD | 1 TB Enterprise NVMe (RAID 10) |
| Network Uplink | 1 Gbps Dedicated Port | 10 Gbps Redundant Uplink |
| Operating System | Ubuntu 24.04 LTS / Debian 12 | Ubuntu 24.04 LTS / Windows Server 2025 RDP |
| Target Models | Llama 3.1 8B, Qwen 2.5 7B, Mistral 7B | Llama 3.3 70B, Qwen 2.5 32B/72B, DeepSeek-R1 |
For high-throughput execution without bottlenecking during matrix multiplications and disk swapping, explore Nextgen Dedicated Servers and high-RAM Pakistani Cloud VPS Instances.
2. Operating System & Kernel-Level Environment Preparation
Before initializing CUDA packages or Python virtual environments, the underlying Linux kernel parameters must be tuned to eliminate filesystem bottlenecks, increase memory mapping limits, and optimize dirty page writebacks during checkpoint writes.
Step 2.1: Base System Update & Essential Toolchain Setup
Connect to your server via SSH:
# Update package repositories and system libraries
sudo apt-get update && sudo apt-get -y upgrade

# Install core build dependencies, C++ toolchains, and monitoring tools
sudo apt-get install -y \
    build-essential \
    cmake \
    git \
    git-lfs \
    curl \
    wget \
    htop \
    iotop \
    nvtop \
    tmux \
    libopenblas-dev \
    pkg-config \
    python3-dev \
    python3-pip \
    python3-venv \
    zlib1g-dev \
    libssl-dev

# Initialize Git LFS for large Hugging Face repository handling
git lfs install
Step 2.2: Memory Virtualization & Storage Swappiness Optimization
When fine-tuning large context windows (8,192 to 32,768 tokens), intermediate gradient states can temporarily spike RAM usage. Configure a high-speed 32GB NVMe swap file and adjust vm.swappiness so the kernel uses swap purely as emergency buffer space without degrading memory access speed:
# Allocate 32GB NVMe swap space
sudo fallocate -l 32G /swapfile
sudo chmod 600 /swapfile
sudo mkswap /swapfile
sudo swapon /swapfile

# Ensure persistent mount across reboots
echo '/swapfile none swap sw 0 0' | sudo tee -a /etc/fstab

# Tune kernel virtual memory parameters
sudo tee /etc/sysctl.d/99-llm-tuning.conf << 'EOF'
# Prevent aggressive memory swapping
vm.swappiness = 10

# Increase maximum memory map areas for PyTorch memory allocators
vm.max_map_count = 1048576

# Optimize dirty page ratios for fast NVMe writes during checkpoint saves
vm.dirty_background_ratio = 5
vm.dirty_ratio = 10

# Network stack buffer sizing for rapid weight downloads
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216
net.ipv4.tcp_rmem = 4096 87380 16777216
net.ipv4.tcp_wmem = 4096 65536 16777216
EOF

# Apply kernel parameters immediately
sudo sysctl --system
3. High-Performance Python & CUDA Environment Setup
To maximize throughput and prevent dependency collisions, establish an isolated Python 3.11/3.12 environment with optimized wheels for PyTorch, Triton, and FlashAttention-2.
# Create dedicated workspace directory
mkdir -p ~/llm-workspace/{models,datasets,adapters,quantized,scripts}
cd ~/llm-workspace

# Create and activate Python virtual environment
python3 -m venv venv
source venv/bin/activate

# Upgrade package management tools
pip install --upgrade pip setuptools wheel
Installing PyTorch and Accelerated Compute Libraries
Install PyTorch built with CUDA support (or ROCm for AMD accelerators):
# Install PyTorch with CUDA 12.4 support
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu124

# Verify CUDA / CPU Compute availability
python3 -c "import torch; print(f'PyTorch: {torch.__version__} | CUDA Available: {torch.cuda.is_available()}')"
Installing Unsloth, Hugging Face Transformers, and Acceleration Toolkits
Unsloth delivers custom OpenAI Triton kernels that replace PyTorch’s native backpropagation implementation. This slashes VRAM consumption by 70% and accelerates fine-tuning speeds by 2x to 5x without any loss in model accuracy.
# Install Unsloth and standard AI ecosystem libraries
pip install --no-deps "unsloth[cu124-torch240] @ git+https://github.com/unslothai/unsloth.git"

# Install complementary training and quantization packages
pip install \
    transformers \
    datasets \
    accelerate \
    peft \
    trl \
    bitsandbytes \
    scipy \
    sentencepiece \
    protobuf \
    huggingface_hub \
    vllm
4. Dataset Engineering: Curating & Formatting Multilingual Urdu Corpora
A common obstacle in localized Pakistani NLP (such as legal contract parsing, Urdu customer support bots, and Roman Urdu sentiment classification) is subword token fragmentation.
Standard Western-trained tokenizers (like raw LLaMA byte-level BPE) often split a single Urdu word into 4 to 8 individual byte tokens. This quadruples the sequence length, degrades context retention, and inflates inference latency.
┌──────────────────────────────────────────────────────────────────────────────────────────┐
│                            TOKEN FRAGMENTATION COMPARISON                                │
├──────────────────────────────────────────────────────────────────────────────────────────┤
│                                                                                          │
│  Sentence: "پاکستان میں کلاؤڈ کمپیوٹنگ کی جدید سہولیات"                                   │
│                                                                                          │
│  • Naive Subword Tokenizer: [پاک][ست][ان] [م][ی][ں] [کل][او][ڈ] ... (28 Tokens!)         │
│  • Optimized Regional Tokenizer / Qwen 2.5: [پاکستان] [میں] [کلاؤڈ] ... (7 Tokens!)       │
│                                                                                          │
│  Result: 75% Lower Inference Latency, 4x Larger Effective Context Window                 │
│                                                                                          │
└──────────────────────────────────────────────────────────────────────────────────────────┘
Modern architectures such as Qwen 2.5 and Llama 3.3 possess expansive 152K+ vocabularies that handle Urdu Unicode scripts and Roman Urdu transliterations natively.
Creating the Instruction-Tuning Dataset
Structure your training dataset using standard ChatML or Alpaca format. Save your training data in ~/llm-workspace/datasets/urdu_enterprise_qa.json:
[
  {
    "instruction": "آپ کون ہیں اور آپ کیا کام سرانجام دیتے ہیں؟",
    "input": "",
    "output": "میں ایک خود مختار، محفوظ اور جدید پاکستانی لارج لینگویج ماڈل ہوں، جسے نیکسٹ جن ہوسٹنگ (Nextgen Hosting) کے تیز رفتار NVMe سرورز پر تربیت دی گئی ہے۔ میرا مقصد کلاؤڈ سسٹمز، سافٹ ویئر ڈیولپمنٹ، اور کاروباری آٹومیشن میں درست اور جامع رہنمائی فراہم کرنا ہے۔"
  },
  {
    "instruction": "Explain how to securely configure an SSH daemon on a remote Linux VPS in Urdu.",
    "input": "",
    "output": "ریموٹ لینکس VPS پر SSH ڈیمن کو محفوظ بنانے کے لیے درج ذیل اقدامات کریں:\n1. ڈیفالٹ پورٹ 22 کو تبدیل کر کے غیر روایتی پورٹ (مثلاً 2244) پر منتقل کریں۔\n2. /etc/ssh/sshd_config میں `PermitRootLogin no` سیٹ کر کے روٹ لاگ ان غیر فعال کریں۔\n3. پاس ورڈ لاگ ان کی جگہ RSA/Ed25519 پبلک کی (SSH Keys) کو لازمی قرار دیں۔\n4. غیر متعلقہ آئی پیز کو بلاک کرنے کے لیے UFW یا CSF فائر وال کنفیگر کریں۔"
  }
]
5. End-to-End QLoRA Fine-Tuning Pipeline with Unsloth
Now we construct the fine-tuning script. This script loads Llama-3.3-8B-Instruct (or Qwen-2.5-7B/14B-Instruct) in 4-bit precision via BitsAndBytes, injects Low-Rank Adapters (LoRA) into the attention and MLP projections, maps the instruction template, and executes gradient descent using AdamW.
Save the following production script as ~/llm-workspace/scripts/train_qlora.py:
#!/usr/bin/env python3
"""
Production QLoRA Fine-Tuning Script using Unsloth
Optimized for Dedicated NVMe VPS / Bare-Metal RDP Infrastructure
"""

import os
import torch
from datasets import load_dataset
from unsloth import FastLanguageModel
from trl import SFTTrainer
from transformers import TrainingArguments

# ==========================================
# 1. Configuration & Hyperparameters
# ==========================================
MAX_SEQ_LENGTH = 4096       # Extended context window
DTYPE = None                # Auto-detect (Float16 for older, Bfloat16 for modern CPUs/GPUs)
LOAD_IN_4BIT = True         # 4-bit quantization for minimal VRAM footprint

MODEL_NAME = "unsloth/Llama-3.2-3B-Instruct"  # Base model (change to Llama-3.3-8B or Qwen2.5-7B)
DATASET_PATH = "/root/llm-workspace/datasets/urdu_enterprise_qa.json"
OUTPUT_DIR = "/root/llm-workspace/adapters/urdu_llama_qlora"

print("==> Loading Base Model with Unsloth FastLanguageModel...")
model, tokenizer = FastLanguageModel.from_pretrained(
    model_name=MODEL_NAME,
    max_seq_length=MAX_SEQ_LENGTH,
    dtype=DTYPE,
    load_in_4bit=LOAD_IN_4BIT,
)

# ==========================================
# 2. Configure LoRA / PEFT Adapters
# ==========================================
print("==> Attaching LoRA Adapters to Attention & MLP Projections...")
model = FastLanguageModel.get_peft_model(
    model,
    r=16,                         # Rank matrix dimension
    target_modules=[
        "q_proj", "k_proj", "v_proj", "o_proj",
        "gate_proj", "up_proj", "down_proj"
    ],
    lora_alpha=16,                # Scaling parameter
    lora_dropout=0,               # Unsloth supports optimized 0 dropout
    bias="none",
    use_gradient_checkpointing="unsloth",  # 70% VRAM reduction via smart recomputation
    random_state=3407,
    use_rslora=False,
    loftq_config=None,
)

# ==========================================
# 3. Formatting & Prompt Template
# ==========================================
alpaca_prompt = """Below is an instruction that describes a task, paired with an input that provides further context. Write a response that appropriately completes the request.

### Instruction:
{}

### Input:
{}

### Response:
{}"""

EOS_TOKEN = tokenizer.eos_token

def formatting_prompts_func(examples):
    instructions = examples["instruction"]
    inputs       = examples["input"]
    outputs      = examples["output"]
    texts = []
    for instruction, input_text, output in zip(instructions, inputs, outputs):
        text = alpaca_prompt.format(instruction, input_text, output) + EOS_TOKEN
        texts.append(text)
    return {"text": texts}

print(f"==> Ingesting Dataset from {DATASET_PATH}...")
dataset = load_dataset("json", data_files=DATASET_PATH, split="train")
dataset = dataset.map(formatting_prompts_func, batched=True)

# ==========================================
# 4. SFT Training Execution
# ==========================================
print("==> Initializing SFT Trainer...")
trainer = SFTTrainer(
    model=model,
    tokenizer=tokenizer,
    train_dataset=dataset,
    dataset_text_field="text",
    max_seq_length=MAX_SEQ_LENGTH,
    dataset_num_proc=4,
    packing=False,  # Set to True for massive datasets to speed up training
    args=TrainingArguments(
        per_device_train_batch_size=2,
        gradient_accumulation_steps=4,
        warmup_steps=10,
        max_steps=100,             # Adjust to 500-2000 for full epoch training
        learning_rate=2e-4,
        fp16=not torch.cuda.is_bf16_supported(),
        bf16=torch.cuda.is_bf16_supported(),
        logging_steps=10,
        optim="adamw_8bit",        # 8-bit optimizer to conserve memory
        weight_decay=0.01,
        lr_scheduler_type="linear",
        seed=3407,
        output_dir="outputs",
        report_to="none",          # Disable external wandb/tracker telemetry
    ),
)

print("==> Starting Model Training...")
trainer_stats = trainer.train()

print(f"==> Training Complete! Saving LoRA Adapters to {OUTPUT_DIR}...")
model.save_pretrained(OUTPUT_DIR)
tokenizer.save_pretrained(OUTPUT_DIR)
print("==> Adapters successfully serialized.")
Running the Training Job in Background Session
To prevent sudden disconnection when managing servers over long-distance SSH connections, run your training inside a tmux session:
# Launch persistent session
tmux new -s llm-train

# Activate virtual environment and run training script
source ~/llm-workspace/venv/bin/activate
python3 ~/llm-workspace/scripts/train_qlora.py
Detach from tmux by pressing Ctrl + B, then D. You can safely log off your workstation while the server executes the training run at full speed. Re-attach at any time with tmux attach -t llm-train.
6. Adapter Merging and Multi-Bit GGUF Quantization with Llama.cpp
Once training is complete, the LoRA delta weights must be merged into the base 16-bit model weights. For production inference on CPU/RAM or budget instances, quantizing the merged model to GGUF format (e.g., q4_k_m, q5_k_m, q8_0) reduces model size by up to 75% while retaining over 99% of original perplexity.
Step 6.1: Direct GGUF Export via Unsloth
Unsloth includes native C++ compilation routines that merge adapters and export GGUF files directly in a single command.
Create ~/llm-workspace/scripts/export_gguf.py:
#!/usr/bin/env python3
"""
Automated LoRA Merge & Multi-Bit GGUF Quantization Exporter
"""

from unsloth import FastLanguageModel

ADAPTER_PATH = "/root/llm-workspace/adapters/urdu_llama_qlora"
EXPORT_DIR = "/root/llm-workspace/quantized"

print("==> Reloading Model and Adapters for Export...")
model, tokenizer = FastLanguageModel.from_pretrained(
    model_name=ADAPTER_PATH,
    max_seq_length=4096,
    dtype=None,
    load_in_4bit=False,  # Load in full float16 to perform lossless weight merging
)

# Export to GGUF format with standard 4-bit medium quantization
print("==> Merging weights and quantizing to GGUF (q4_k_m)...")
model.save_pretrained_gguf(
    f"{EXPORT_DIR}/urdu-model-q4_k_m",
    tokenizer,
    quantization_method="q4_k_m"
)

# Also export high-precision 8-bit quantization for enterprise accuracy
print("==> Exporting high-precision 8-bit GGUF (q8_0)...")
model.save_pretrained_gguf(
    f"{EXPORT_DIR}/urdu-model-q8_0",
    tokenizer,
    quantization_method="q8_0"
)

print("==> Export pipeline finished successfully!")
Run the export script:
python3 ~/llm-workspace/scripts/export_gguf.pyStep 6.2: Compiling Llama.cpp from Source for Hardware Acceleration
To run the quantized GGUF model with maximum multi-threaded CPU performance (using AVX-512 and OpenBLAS instructions), compile llama.cpp directly on the host:
cd ~/llm-workspace
git clone https://github.com/ggerganov/llama.cpp
cd llama.cpp

# Compile with OpenBLAS and optimized CPU SIMD instructions
cmake -B build -DGGML_BLAS=ON -DGGML_BLAS_VENDOR=OpenBLAS
cmake --build build --config Release -j$(nproc)
Test the quantized model directly in terminal:
./build/bin/llama-cli \
    -m ~/llm-workspace/quantized/urdu-model-q4_k_m/unsloth.Q4_K_M.gguf \
    -p "Below is an instruction that describes a task. Write a response.\n\n### Instruction:\nپاکستان کے کلاؤڈ انفراسٹرکچر کے فوائد بیان کریں۔\n\n### Response:\n" \
    -n 512 \
    -t $(nproc) \
    --temp 0.3
7. Production Serving: High-Concurrency APIs with vLLM & Llama.cpp Server
To expose the fine-tuned model to web applications, e-commerce platforms, customer support chatbots, and internal enterprise dashboards, we can deploy two high-performance serving architectures:
- vLLM Engine: For high-concurrency, asynchronous batched inference using PagedAttention.
- Llama.cpp HTTP Server: For lightweight, ultra-low-memory CPU/NVMe offloaded inference.
┌──────────────────────────────────────────────────────────────────────────────────────────┐
│                           PRODUCTION SERVING TOPOLOGY                                    │
├──────────────────────────────────────────────────────────────────────────────────────────┤
│                                                                                          │
│  [ External Clients / Web & Mobile Apps ]                                                │
│                      │                                                                   │
│                      ▼ (HTTPS Port 443 / SSL Termination)                                │
│  ┌────────────────────────────────────────────────────────────────────────────────────┐  │
│  │ NGINX REVERSE PROXY & RATE LIMITING                                                │  │
│  │ • API Key Authentication & TLS 1.3 Encryption                                      │  │
│  │ • Reverse proxy to local socket / internal port                                    │  │
│  └────────────────────────────────────────────────────────────────────────────────────┘  │
│                      │                                                                   │
│                      ▼ (Internal Port 8000 / Unix Domain Socket)                         │
│  ┌────────────────────────────────────────────────────────────────────────────────────┐  │
│  │ INFERENCE SERVER DAEMON (vLLM / Llama.cpp)                                         │  │
│  │ • Continuous Request Batching & KV Cache Memory Pooling (PagedAttention)           │  │
│  │ • OpenAI-Compatible Endpoints (`/v1/chat/completions`, `/v1/models`)               │  │
│  │ • Monitored by Systemd Unit with Automatic Crash Recovery                          │  │
│  └────────────────────────────────────────────────────────────────────────────────────┘  │
│                                                                                          │
└──────────────────────────────────────────────────────────────────────────────────────────┘
Option A: Serving via Llama.cpp HTTP Server (Systemd Daemon)
Create a dedicated systemd service to run the Llama.cpp server daemon with 24/7 persistence:
sudo tee /etc/systemd/system/llama-server.service << 'EOF'
[Unit]
Description=Llama.cpp High-Performance OpenAI-Compatible Server
After=network.target

[Service]
Type=simple
User=root
WorkingDirectory=/root/llm-workspace/llama.cpp
ExecStart=/root/llm-workspace/llama.cpp/build/bin/llama-server \
    -m /root/llm-workspace/quantized/urdu-model-q4_k_m/unsloth.Q4_K_M.gguf \
    --host 127.0.0.1 \
    --port 8080 \
    --ctx-size 4096 \
    --threads 8 \
    --parallel 4 \
    --cont-batching \
    --alias urdu-llm-v1
Restart=always
RestartSec=5
LimitNOFILE=65536

[Install]
WantedBy=multi-user.target
EOF

# Reload systemd, enable and launch service
sudo systemctl daemon-reload
sudo systemctl enable --now llama-server.service
sudo systemctl status llama-server.service
Option B: High-Throughput Serving via vLLM
vLLM natively supports loading both unquantized merged weights and GGUF quantized models:
# Launch vLLM OpenAI-compatible server on internal port 8000
python3 -m vllm.entrypoints.openai.api_server \
    --model /root/llm-workspace/quantized/urdu-model-q4_k_m/unsloth.Q4_K_M.gguf \
    --port 8000 \
    --host 127.0.0.1 \
    --max-model-len 4096 \
    --gpu-memory-utilization 0.90 \
    --served-model-name "urdu-enterprise-gpt"
8. Enterprise Nginx Reverse Proxy with SSL Termination & API Security
To expose the inference API securely to your frontend applications across Pakistan and internationally, configure Nginx as an SSL reverse proxy with request throttling and bearer token validation.
# Install Nginx and Certbot
sudo apt-get install -y nginx certbot python3-certbot-nginx
Create the Nginx configuration file /etc/nginx/sites-available/llm-api:
# Rate Limiting Zone: 30 requests per minute per IP
limit_req_zone $binary_remote_addr zone=llm_limit:10m rate=30r/m;

server {
    server_name api-llm.yourdomain.pk;

    # Maximum request body size for long context prompts
    client_max_body_size 64M;

    location / {
        limit_req zone=llm_limit burst=10 nodelay;

        proxy_pass http://127.0.0.1:8080;
        proxy_http_version 1.1;

        # Enable SSE (Server-Sent Events) for real-time text streaming
        proxy_set_header Connection '';
        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;

        # Disable buffering to allow instant token streaming
        proxy_buffering off;
        proxy_cache off;
        proxy_read_timeout 300s;
        proxy_send_timeout 300s;
    }

    listen 80;
}
Enable the site configuration and provision a Let’s Encrypt SSL certificate:
sudo ln -s /etc/nginx/sites-available/llm-api /etc/nginx/sites-enabled/
sudo nginx -t
sudo systemctl reload nginx

# Generate SSL certificate (replace with your actual domain)
# sudo certbot --nginx -d api-llm.yourdomain.pk
9. Verifying the Production OpenAI-Compatible Streaming Endpoint
You can now query your dedicated Pakistani NLP model from any standard programming language using the official OpenAI SDK.
Python Client Example with Streaming:
#!/usr/bin/env python3
import os
from openai import OpenAI

# Initialize client pointing to your dedicated VPS endpoint
client = OpenAI(
    base_url="http://127.0.0.1:8080/v1",  # Or https://api-llm.yourdomain.pk/v1
    api_key="none",                      # Handled by proxy or internal token
)

print("==> Submitting Prompt to Fine-Tuned Urdu Model...")

response = client.chat.completions.create(
    model="urdu-llm-v1",
    messages=[
        {
            "role": "system",
            "content": "آپ ایک ماہر کلاؤڈ اور مصنوعی ذہانت کے مشیر ہیں۔"
        },
        {
            "role": "user",
            "content": "نیکسٹ جن ہوسٹنگ کے NVMe سرورز پر ایل ایل ایم چلانے کے اہم تکنیکی فوائد کیا ہیں؟"
        }
    ],
    temperature=0.4,
    max_tokens=512,
    stream=True
)

# Stream response tokens in real-time
for chunk in response:
    content = chunk.choices[0].delta.content
    if content:
        print(content, end="", flush=True)

print("\n")
10. Performance Benchmarks & Engineering Best Practices
When operating production LLM infrastructure on dedicated VPS nodes, adhere to the following optimization protocols:
Benchmarking Throughput & Memory Efficiency
| Optimization Technique | Baseline PyTorch FP16 | Unsloth + QLoRA (4-bit) | GGUF Quantized (Q4_K_M) |
|---|---|---|---|
| VRAM Footprint (8B Model) | ~16.5 GB | ~5.8 GB | ~4.6 GB (RAM / VRAM) |
| Training Speed (Tokens/Sec) | 850 tps | 2,150 tps (2.5x) | N/A (Inference Only) |
| Inference Generation Speed | 22 tokens/sec | 24 tokens/sec | 48 tokens/sec (2.1x) |
| Perplexity Degradation | Baseline (0.00%) | < 0.05% | < 0.12% |
Key Production Takeaways
- Leverage NVMe Direct I/O: Training datasets exceeding 100,000 instruction pairs should reside on high-IOPS NVMe partitions to prevent worker thread stalling during batch pre-fetching.
- Utilize RoPE Frequency Scaling: When extending context length from 4K to 16K or 32K tokens, configure
yarnordynamicRoPE scaling in Unsloth andllama.cppto prevent attention degradation. - Automate Adapter Versioning: Store trained LoRA adapters in Git repositories with Git LFS or Hugging Face Private Hubs using
model.push_to_hub_merged()for seamless CI/CD model promotion. - Deploy Redundant Failover: Maintain an active-passive configuration across multiple Nextgen Cloud VPS instances to guarantee 100% uptime during model hot-swaps.
Summary & Getting Started
Self-hosting localized, fine-tuned Large Language Models provides Pakistani software companies, universities, and enterprises with total data sovereignty, zero per-token third-party API costs, and sub-second inference latency for regional languages.
By combining Unsloth for 2x-5x faster parameter-efficient training, Llama.cpp / GGUF for multi-bit quantization, and vLLM for enterprise-grade serving, you unlock industrial-grade AI capabilities on budget-friendly infrastructure.
Ready to architect your dedicated AI fine-tuning or inference cluster? Explore high-performance Nextgen NVMe Cloud VPS, dedicated GPU-Accelerated Remote Desktop Workstations (RDP), and enterprise Bare-Metal Servers engineered for extreme compute workloads.
